Public Attributes | ||
| size_t | pending | |
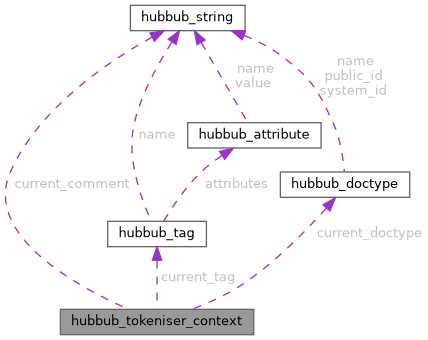
| hubbub_string | current_comment | |
| hubbub_token_type | current_tag_type | |
| hubbub_tag | current_tag | |
| hubbub_doctype | current_doctype | |
| hubbub_tokeniser_state | prev_state | |
| uint8_t | last_start_tag_name [10] | |
| size_t | last_start_tag_len | |
| struct { | ||
| uint32_t count | ||
| bool match | ||
| } | close_tag_match | |
| struct { | ||
| uint32_t count | ||
| } | match_doctype | |
| struct { | ||
| uint32_t count | ||
| uint32_t end | ||
| } | match_cdata | |
| struct { | ||
| size_t offset | ||
| uint32_t length | ||
| uint32_t codepoint | ||
| bool complete | ||
| uint32_t poss_length | ||
| uint8_t base | ||
| int32_t context | ||
| size_t prev_len | ||
| bool had_data | ||
| bool overflow | ||
| hubbub_tokeniser_state return_state | ||
| } | match_entity | |
| struct { | ||
| uint32_t line | ||
| uint32_t col | ||
| } | position | |
| uint32_t | allowed_char | |
Detailed Description
Context for tokeniser
Member Data Documentation
◆ allowed_char
| uint32_t hubbub_tokeniser_context::allowed_char |
Used for quote matching
◆ base
| uint8_t hubbub_tokeniser_context::base |
Base for numeric entities
◆ [struct]
| struct { ... } hubbub_tokeniser_context::close_tag_match |
State for matching close tags
◆ codepoint
| uint32_t hubbub_tokeniser_context::codepoint |
UCS4 codepoint
◆ col
| uint32_t hubbub_tokeniser_context::col |
Current character in line
◆ complete
| bool hubbub_tokeniser_context::complete |
True if match complete
◆ context
| int32_t hubbub_tokeniser_context::context |
Context for named entity search
◆ count
| uint32_t hubbub_tokeniser_context::count |
Index into "DOCTYPE"
Index into "[CDATA["
◆ current_comment
| hubbub_string hubbub_tokeniser_context::current_comment |
Current comment text
◆ current_doctype
| hubbub_doctype hubbub_tokeniser_context::current_doctype |
Current doctype
◆ current_tag
| hubbub_tag hubbub_tokeniser_context::current_tag |
Current tag
◆ current_tag_type
| hubbub_token_type hubbub_tokeniser_context::current_tag_type |
Type of current_tag
◆ end
| uint32_t hubbub_tokeniser_context::end |
Index into "]]>"
◆ had_data
| bool hubbub_tokeniser_context::had_data |
Whether we read anything after &#(x)?
◆ last_start_tag_len
| size_t hubbub_tokeniser_context::last_start_tag_len |
Length of last start tag
◆ last_start_tag_name
| uint8_t hubbub_tokeniser_context::last_start_tag_name[10] |
Name of the last start tag emitted
◆ length
| uint32_t hubbub_tokeniser_context::length |
Length of entity
◆ line
| uint32_t hubbub_tokeniser_context::line |
Current line of input
◆ match
| bool hubbub_tokeniser_context::match |
◆ [struct]
| struct { ... } hubbub_tokeniser_context::match_cdata |
State for matching cdata
◆ [struct]
| struct { ... } hubbub_tokeniser_context::match_doctype |
State for matching doctype
◆ [struct]
| struct { ... } hubbub_tokeniser_context::match_entity |
Entity matching state
◆ offset
| size_t hubbub_tokeniser_context::offset |
Offset in buffer
◆ overflow
| bool hubbub_tokeniser_context::overflow |
Whether this entity has has overflowed the maximum numeric entity value
◆ pending
| size_t hubbub_tokeniser_context::pending |
Count of pending chars
◆ [struct]
| struct { ... } hubbub_tokeniser_context::position |
Position in source data
◆ poss_length
| uint32_t hubbub_tokeniser_context::poss_length |
Optimistic length when matching named character references
◆ prev_len
| size_t hubbub_tokeniser_context::prev_len |
Previous byte length of str
◆ prev_state
| hubbub_tokeniser_state hubbub_tokeniser_context::prev_state |
Previous state
◆ return_state
| hubbub_tokeniser_state hubbub_tokeniser_context::return_state |
State we were called from
The documentation for this struct was generated from the following file:
- XenevaOS/Ports/CssLibs/libhubbub/src/tokeniser/tokeniser.c
